
University Of Rochester And Adobe Are Frontrunners In Microsoft COCO Image Captioning Challenge
Computer scientists from the University of Rochester and Adobe have joined hands in a bid to outperform Google, Microsoft, Baidu/UCLA, Stanford University, University of California Berkeley, University of Toronto/Montreal and other star companies and research institutes in the Microsoft COCO Image Captioning Challenge, with the help of a new amalgamated form of computer generated autonomous captioning of images.
The team explained that they have taken help from two proprietary approaches known as âtop-downâ and âbottom-upâ and united them to engineer a novel method that is error free and provides almost an accurate phrase corresponding to the particular image. In the first approach, the image is interpreted and then words are framed accordingly, following a mannered structure. On the other hand, in the second process, it fixes words according to the image objects and then combines them to form a sentence.

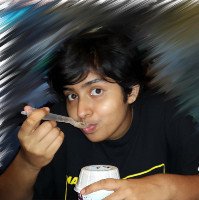
Google caption: âA baby is eating a piece of paper.â
Rochester ATT caption: âA baby with a toothbrush in its mouth."
Different groups who also participated in the challenge have tried to mix these two approaches together, but they mostly emphasized on the most important aspect of an image. However, the winning team decided to ascertain the importance relying on an algorithmâs decision. Computer image captioning greatly depends on two massive research topics of artificial intelligence, namely natural language processing and computer vision. The first subject helps the system to âlearnâ from a stack of image sets while the latter helps in forming words and compilation.
The team leader of the research project, Professor Jiebo Luo expressed that their research product was trained under different situations and texts. The key goal of their product was related to the most important feature of an image and assigned a word semantically correct according to the meaning of the image. The complete paper was published on 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR).
Source: <a href="https://www.rochester.edu/newscenter/university-of-rochester-team-leads-competition-for-best-image-captions-by-computers/" target="_blank" rel="nofollow noopener noreferrer">Paying attention to words, not just images, leads to better captions : News Center</a>